How Does AI Image Detection Work? Methods, Signals, and Why Detectors Make Mistakes
Short answer: An AI image detector is a classifier trained on labeled real and AI-generated images. It outputs a probability, such as “87% AI-generated,” not a verdict. Its accuracy depends mostly on how broad its training data was, so its errors follow predictable patterns.
Detectors learn to separate real from AI-generated photos using labeled examples. Their output is a probability, not a verdict. Detectors no longer rely on obvious flaws like warped hands. They use statistical patterns that humans cannot name. Popular detection tools offer a useful starting point, but no single score settles the question, and professionals should read the best results alongside other evidence.
Key Takeaways
- The core answer: A detector is a trained classifier that learns to separate real and AI-generated images from labeled examples.
- The output is a score: A result like “92% AI” is a probability, not a verdict. Treat it as evidence.
- Accuracy follows training breadth: A detector trained on few generators can miss images from new ones.
- Fingerprints don’t transfer: Each architecture leaves its own pattern, so detectors generalize poorly.
- Check vendor claims: A high score on one dataset does not guarantee performance on your images.
- Use the Trust-Weight Checklist: Score five questions from 0 to 2. A low total calls for investigation, not a finding.
Table of Contents
- What an AI Image Detector Actually Produces
- Why Detection Matters Now
- How Trained Classifiers Differ From Rule-Based Systems
- Inside the Pipeline: Features, Fingerprints and Frequency Analysis
- From Model Output to a Probability Score
- Why Detectors Make Mistakes
- Conclusion and Summary
What an AI Image Detector Actually Produces
An AI image detector produces a probability, not a verdict. It is a trained classifier, shown large numbers of real photographs and AI-generated images, that learns which patterns tend to separate the two. Upload a photo and you might get “87% AI-generated.” That is a score to weigh, not a ruling, and the content of the photo itself still needs independent analysis.
WeDetect’s explainer on how AI image detectors work calls the detector a trained classifier, not a rulebook. Treat a score as evidence, not a verdict. The Trust-Weight Checklist later in this article shows how.
Why the Training Set Sets the Ceiling
A detector can only recognize what resembles its training data. Any generator its builders left out is a blind spot, so lab accuracy and real-world accuracy can diverge. Compressed or resized media can also perform differently from lab images, which is why a popular tool’s result on one file may not hold on another. Its learning is only as broad as the text and images it was trained on, so check the terms a vendor publishes about its training data.
Why Detection Matters Now
Synthetic images now look photographic, so human judgment alone is no longer a dependable filter. Detection matters most where a false image does damage: newsrooms verifying user-submitted content, trust-and-safety teams screening uploads, and insurers reviewing damage claims. A detector gives them a measurable signal before they decide whether to trust a picture, and learning to read that signal is now a core professional skill.
Why Visual Inspection Stopped Working
Advice to look for warped hands or garbled text has aged badly, because current generators handle these details well. A detector learns separating patterns from millions of labeled images, many invisible to the eye.
Who Relies on Detection Tools
The main users are professionals whose decisions depend on provenance. Tools such as Undetectable AI’s image detector cover generators US readers meet daily, including DALL·E, Stable Diffusion, Midjourney, Ideogram, Flux, Bing Image Creator, Nano Banana and Adobe Firefly. These users need a score they can act on, not just a yes or no, and popular social media platforms make that score even more important.
How Trained Classifiers Differ From Rule-Based Systems
Early synthetic-image detection relied on hand-written rules, such as checking for extra fingers or warped text. These rules worked until generators improved and the flaws they targeted disappeared. A learned classifier instead studies a large set of labeled images and finds the statistical patterns that separate real from synthetic, including signals no person would think to name.
What a Rule-Based Detector Would Check
A rule-based detector is only as good as its author’s list, and newer models can quietly remove the flaws each rule targets. Rules also misfire on unusual but genuine photos.
How Training Replaces Hand-Written Rules
Training replaces the rulebook with examples. The model adjusts its internal weights each time it misjudges an image, gradually building a decision boundary from data. As WeDetect’s explainer notes, breadth of training data matters more than clever tricks for real-world performance.
Inside the Pipeline: Features, Fingerprints and Frequency Analysis
Most detectors do not look for a single telltale flaw. They rely on statistical fingerprints. Understanding the pipeline shows why those fingerprints sometimes mislead, and why popular image detection tools can still disagree on the same AI-generated images. Users comparing detection options often find that each tool provides a different view of the same content, and works from different training data.
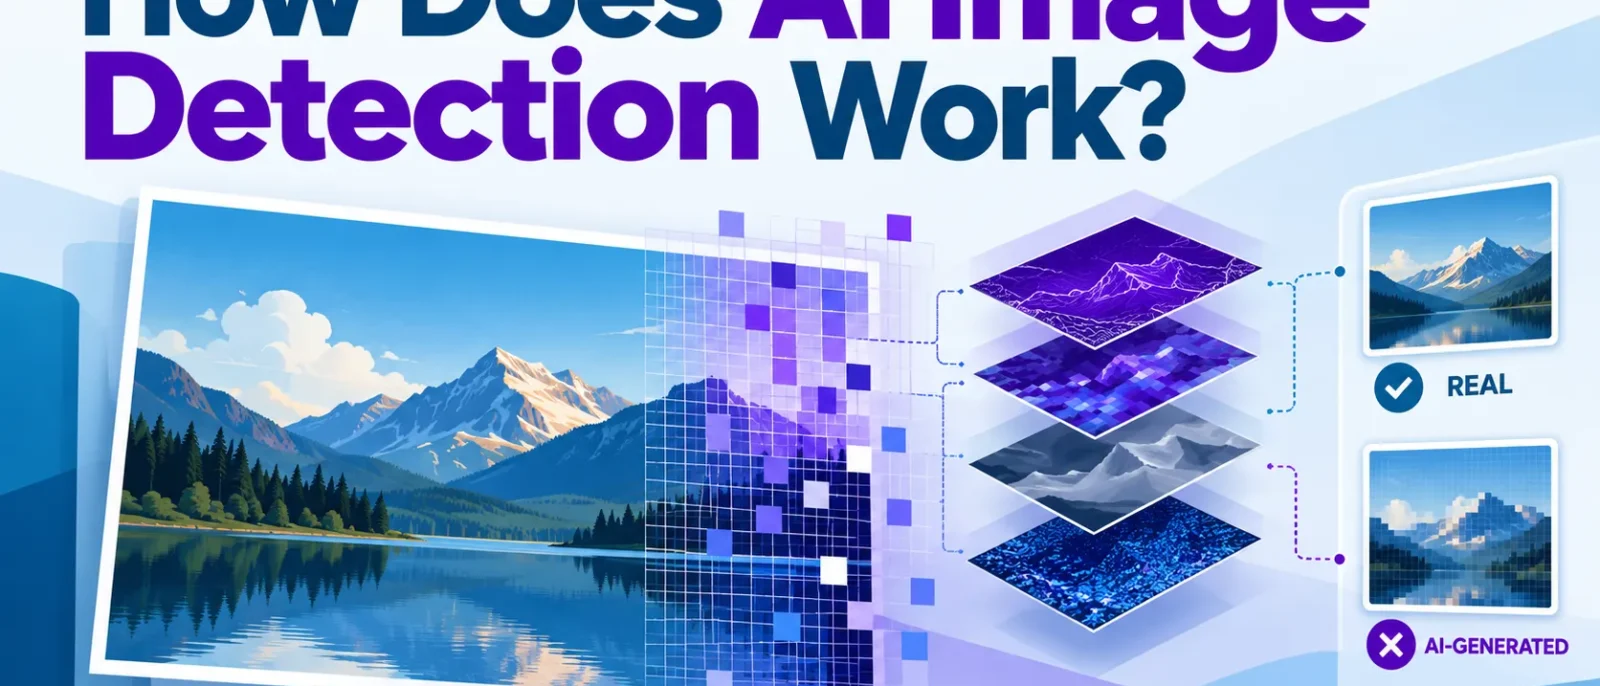
Here is how one image moves through the classifier. The file arrives as a grid of pixel values. A neural network, typically a convolutional neural network (CNN), a vision transformer, or a CLIP-style encoder, compresses that grid into numbers describing texture, lighting, edges and structure. A final layer turns those numbers into a probability, based on patterns learned from synthetic images in the training set.
The output is a learned match, not a check against fixed rules. The same image can therefore score differently on another detector trained on other data. Training data is rarely published in full, and it shapes what a tool can reliably catch. Anyone trying to detect AI-generated images should treat any single score as one input, not a verdict.
Statistical Fingerprints and Generator Traces
Generative models leave signatures in their output. Research in the Journal of Imaging describes GAN architectures inserting a specific pattern into each image as a distinct fingerprint. A detector learns the fingerprints of the generators it saw, so it often generalizes poorly to unfamiliar architectures. Check which generators a tool lists before relying on its results.
Frequency-Domain Analysis
Some detectors apply a Fourier transform, which converts pixels into frequency components, and look for repeating artifacts in the high-frequency spectrum. These signals are fragile, since recompression or resizing can alter them. They work best as one feature among many, not as a standalone test.
From Model Output to a Probability Score
A detector’s final layer outputs a number between 0 and 1 for each class, which the tool rescales into a percentage. That figure is the model’s confidence in its own pattern match, not a measured fact about how the image was made. Undetectable.ai says its detector “consistently achieves high accuracy rates,” while conceding that no detection tool is 100% perfect.
Reading a Confidence Score
Treat the number as evidence to weigh. Three questions help:
- Is it a probability or a label? A score of 92% means the image resembles the AI examples the model learned from, to that degree of confidence.
- Which generator is involved? Scores are most reliable when the generator is in the training set.
- Does a second check agree? Run the image through another tool and look for provenance, such as original files or source context.
Choosing a Threshold for Your Use Case
Set two thresholds before reviewing any image. For example, take no action below 30% and escalate for human review above 80%. Gather more evidence in between. The higher the cost of a wrong call, the wider the review band should be.
Worked example. A claims team scores a submitted photo at 85%, which triggers escalation. The adjuster finds camera metadata and a matching earlier upload, and a second tool scores it at 40%. The provenance evidence clears the image. Without the second check, the single score would have caused a false rejection.
The Trust-Weight Checklist
Score each question from 0 to 2, then act on the total:
| Question | Score range | Action |
|---|---|---|
| 1. Was the generator likely in the detector’s training set? | 0 (unknown) to 2 (confirmed) | Low scores: treat the result as weak evidence |
| 2. Does the tool publish results across several generators? | 0 (no) to 2 (yes, with figures) | Low scores: check a second tool |
| 3. Is the score a probability rather than a binary label? | 0 (label only) to 2 (probability) | Label-only output: do not rely on it alone |
| 4. Has the result been checked against other tools or provenance? | 0 (no check) to 2 (independent agreement) | No check: gather evidence before acting |
| 5. Would a wrong answer cause harm? (Lower harm scores higher.) | 0 (severe harm) to 2 (minor harm) | High harm with a low total: escalate to a person |
| Total (0 to 10) | Action |
|---|---|
| 0 to 3 | Low. Treat as a prompt for further investigation, not a finding. |
| 4 to 7 | Moderate. Gather more evidence before relying on the score. |
| 8 to 10 | High. The score can carry more weight, though it still does not prove origin on its own. |
The checklist is a way to decide how far to trust a score. It does not establish how an image was made.
Why Detectors Make Mistakes
Three failure modes follow from how detectors are trained:
- Unseen generators: Images from models outside the training set can slip through, with only a few percent caught in some benchmarks.
- Processed real photos: Heavily edited or compressed genuine images can get flagged.
- Evasion: Deliberate editing or re-compression can strip the cues detectors rely on.
The first failure is the most dangerous and the most overlooked. A strong AI score on a popular generator deserves more trust than the same score on a model the detector has never seen. Knowing which case you are in is the key skill for reading a score on how does AI image detection work.
When the Detector and the Origin Disagree
When a detector and an image’s origin conflict, origin evidence usually deserves more weight. Check file metadata, trace the image to its source, and confirm the context in which it appeared. A detector is one provenance signal among others, and reviewers should treat its output as a different kind of evidence from documented origin.
Worked Example: Applying a Decision Threshold
A team sets a 90% escalation threshold. An image scores “87% AI-generated,” below the threshold, but shows a generator family the tool documents. The team traces the file, finds no camera metadata, and sends it for manual review. The threshold did not decide the outcome. It only set the point where human judgment took over.
Trust-Weight Checklist
Score each question, then total the points and apply the action. Use this checklist to frame the content you evaluate and to detect ai-generated images more consistently across your team.
| Question | Score range | Action at total |
|---|---|---|
| Is the generator listed in the tool’s documented coverage? | 0 (no) to 3 (yes, multiple) | 0 to 4: weak evidence. 5 to 7: one input. 8 to 10: substantial weight. |
| Does a second tool agree? | 0 (disagrees) to 3 (agrees) | |
| Does provenance evidence (metadata, original source) agree? | 0 (conflicts) to 4 (agrees) |
Conclusion and Summary
An AI image detector is a trained classifier, not a rulebook. It outputs a probability, such as “87% AI-generated,” based on patterns learned from labeled examples. Its reliability depends on how broad its training data was. Treat its output as one strong input, not proof on its own.
Read the score as evidence, not a verdict. Before acting on it, ask: Was the generator likely in the training set? Does the tool report results across several generators? Does another tool or a provenance source agree? If the total is low, treat the score as a prompt for further investigation.
Can an AI image detector prove an image is fake?
No. A detector estimates how closely an image resembles its AI-generated training examples. Treat a high score as a reason to investigate further, and check the file’s provenance, original source and context.
Why does a detector give a different score for the same image?
Detectors differ in training data, architecture and how they convert outputs into percentages. Resizing or re-compressing a file can also shift the score. A score that moves between tools or uploads signals uncertainty.
Do AI image detectors work on every generator?
No. A detector is strongest on the generators it was trained on. Research published in MDPI notes that detectors for GAN-generated images struggle to generalize to other GAN architectures. Sightengine’s detector covers Nano Banana, GPT 2, Grok Imagine, Midjourney, DALL-E 3, Imagen 3 and 4, Stable Diffusion (SD 1.5, SDXL, SD3), Flux, Ideogram, Adobe Firefly, Bing Image Creator, and GAN-based face generators. Check a tool’s list before relying on it.
Can editing or compressing an image fool a detector?
Yes. Cropping, heavy compression, filters and regeneration can remove the traces a detector relies on. A low AI score never proves an image is authentic.
Why do detectors sometimes flag real photos as AI?
Heavily sharpened, denoised or compressed real photos can carry patterns similar to synthetic training examples. Before acting on a flag, check the original camera file or the photographer’s source.
How accurate are AI image detection tools?
Accuracy varies by tool, generator and dataset, and vendor claims are hard to verify independently. Ask whether a tool publishes results across several generators, then cross-check with a second tool and provenance evidence. Frequently asked questions about tool accuracy are worth checking against independent tests.
Disclosure: digitalmarketingtools.ai is sponsored by Digimetrics.ai. Sponsored Highlights are clearly labelled advertising. Our reviews, comparisons and guides are written to be useful and fair regardless of who sponsors the site. Read the full disclosure.