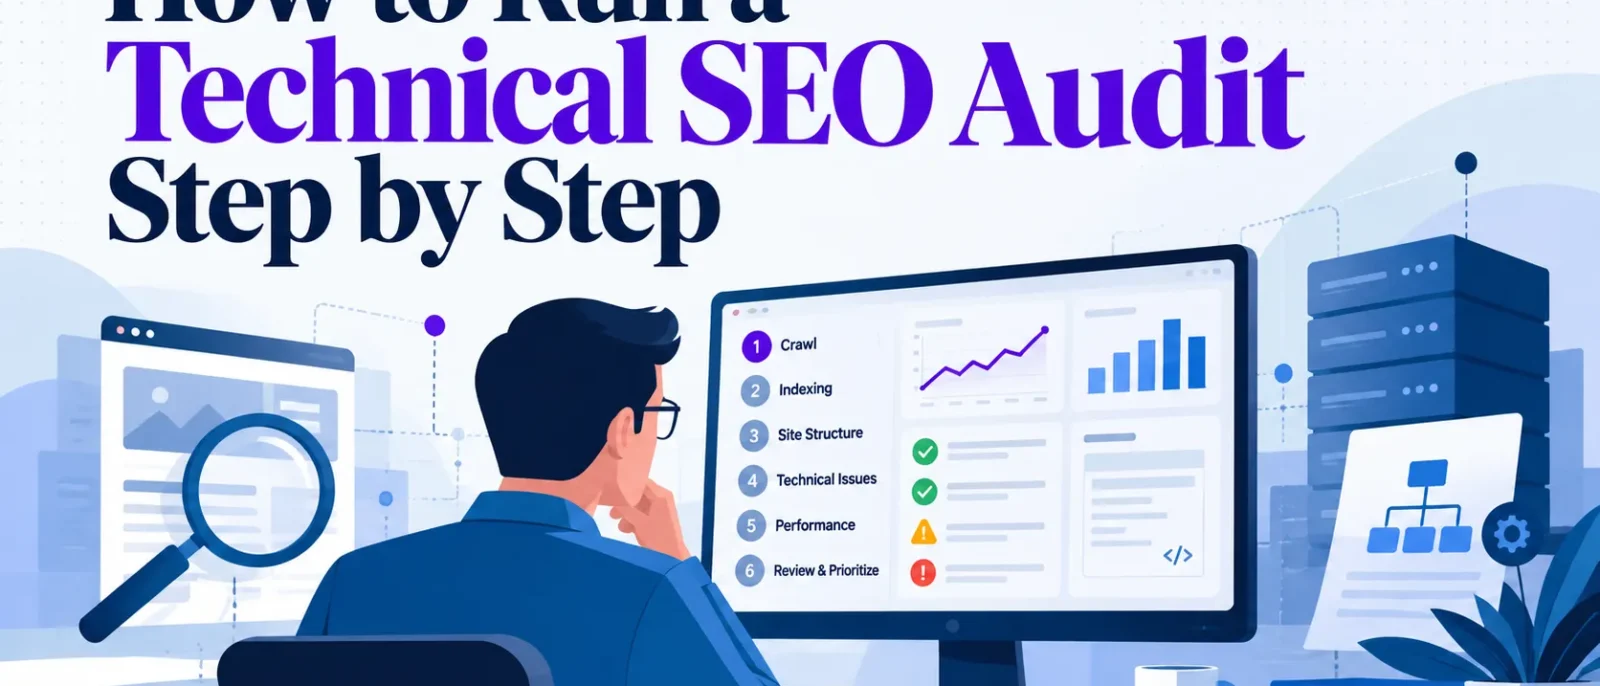
How to Run a Technical SEO Audit Step by Step
Many websites lose search visibility for reasons nobody has examined closely. A page Google cannot crawl, a misdirected canonical tag, or a sitemap listing redirecting URLs quietly limits organic visibility. Google processes over 8.5 billion searches every day, and unindexed pages are invisible to most of that demand. Learning how to run a technical SEO audit is the first step toward finding these blockers.
A technical SEO audit finds these blockers, including the SEO issues that keep pages out of a search engine index. This guide sets out a clear sequence for large and mid-sized sites, plus a way to rank findings into a priority fix list. Running a site audit this way helps teams separate technical blockers from content gaps.
Neil Patel’s step-by-step guide to a successful SEO audit makes a similar case for working through the technical layer before content. The sequence below follows that logic, with an added scoring step so the most damaging issues come first. Applying best practices at each stage keeps the audit consistent across teams.
Key Takeaways
- A technical SEO audit pays off only when it ends in a ranked fix list, not a long list of warnings.
- Score each finding on evidence strength and on how much it blocks crawling, rendering or indexing.
- Start with crawl and indexation blockers. Lydia Rogers lists these first for large sites.
- Confirm tool warnings against Google Search Console and log-file data before acting.
- Run a full audit every three to six months, with lighter checks in between.
- Attach evidence to each developer ticket so fixes get made.
Table of Contents
- What a Technical SEO Audit Is and When to Run One
- Before You Start: Setting Up Your Audit Toolkit
- Step 1: Crawl the Site and Identify Crawl Issues
- Step 2: Check Indexation and Analyze Crawl Budget
- Step 3: Consolidate URL Canonicalization and Site Versions
- Step 4: Analyze JavaScript Rendering and Crawlability
- Step 5: Check Site Speed, Mobile Responsiveness and Core Web Vitals
- Step 6: Validate Structured Data and Schema Markup
- Ranking Findings with the Impact-Evidence Priority Matrix
- Conclusion and Next Steps
- Frequently Asked Questions
What a Technical SEO Audit Is and When to Run One
What a technical audit checks, and what it does not
A technical SEO audit examines a website’s framework to find what stops search engines from crawling, rendering, indexing and ranking its pages. Studiohawk describes an effective SEO audit as one that scrutinises a website’s technical framework to identify impediments to search engine performance. The audit covers crawlability, indexation, site architecture, redirects, canonical tags, sitemaps, robots.txt, structured data, internal linking, duplicate content, thin content, mobile responsiveness and Core Web Vitals, including page speed.
It does not judge content quality, keyword targeting or backlinks. Those belong to content and off-page audits. Keeping scope tight matters. An audit that drifts into content opinions produces a long list with no clear order of work. A focused site audit that stays on the technical framework is far more useful.
How often to audit (every 3 to 6 months, with lighter checks in between)
Run a full audit every three to six months. Between audits, schedule a crawl that flags new broken links, redirect chains and noindexed pages. Check the Page indexing and Core Web Vitals reports in Google Search Console weekly.
Sites that release often need these lighter checks most. One deployment can break canonical tags or robots rules across thousands of URLs overnight, so these routine checks are important for catching regressions early.
Why a small set of issues drives most of the result
Most ranking damage comes from a small number of problems. Webyes puts this at roughly 20 percent of findings, mostly crawlability, indexing and Core Web Vitals problems, accounting for around 80 percent of the result. Treat that ratio as a general practitioner observation rather than a fixed rule. Solomon Goodman, writing on Quora, makes a similar point: the biggest wins often come from fixing speed, mobile issues and crawl errors.
An audit should therefore rank findings rather than count them. A flat list that treats a cosmetic meta description warning the same as a robots.txt rule blocking a category section sends teams to the wrong fixes first. This guide scores each finding on evidence strength, crawl-to-index impact and effect on user experience and on-page SEO. Ranking the results of several SEO audits side by side makes the priority order clearer.
Before You Start: Setting Up Your Audit Toolkit
Three things need to be in place before you crawl anything: a crawler, Google Search Console and a second source that shows what bots actually request. Performing a technical SEO audit of your site starts with these tools, and each one answers a different question.
Crawling tools and what each one is good for
A crawler copies your site the way a bot would. It follows internal links and records status codes, titles, canonicals, robots directives and internal link counts. Most in-house teams use Screaming Frog or Sitebulb. Screaming Frog suits fast, rules-driven crawls. Sitebulb adds visual reporting and prioritised hints, which helps when you explain findings to non-specialists. Both are useful for running SEO audits on mid-sized and large sites.
Note whether JavaScript rendering was on and which user agent you set, because both change the result. Treat the output as a hypothesis, not a verdict. A crawler will flag pages blocked by robots.txt as errors even when they were never meant to rank. Check how the crawl handles the mobile user agent as well, since mobile rendering can differ from desktop.
Google Search Console and manual search checks
Search Console is the source of truth for how Google has indexed your site. The Pages report shows which URLs are indexed, which are excluded and why. The Core Web Vitals report uses field data from real Chrome users, which is important for judging site speed as visitors experience it. Pair it with PageSpeed Insights for field and lab numbers on a single URL.
Run a site: search on your key templates and compare the result count against the pages you intend to rank. These checks take minutes and give you a quick reality test before you trust any export.
Logfile and analytics data as a second opinion
A crawler simulates a bot. Your server logs record what bots actually requested. Navneet Singh makes this point in a Quora discussion on logfile analysis, which shows what happens as a search engine crawls your website. Filter the logs for Googlebot, count hits per URL per week and compare the totals with your crawl export. Watch for pages Googlebot hits often that your crawler rates low priority, and linked pages that never appear in the logs.
Analytics adds the commercial view. A page that earns traffic but returns errors in the logs moves to the front of the queue. Log each source against your findings so every finding carries its own evidence trail.
Step 1: Crawl the Site and Identify Crawl Issues
A crawl shows the site the way a search engine’s crawler sees it, so it is the first thing to run in any technical seo audit of a website. Tools such as Screaming Frog or Sitebulb fetch every reachable URL, record its status code and map how pages link together. Set the crawler to follow redirects, respect robots.txt and use a user agent close to Googlebot’s.
Running a full crawl and reading the results
Export the full crawl before reading anything in the interface, then sort by status code and crawl depth. Pages five or more clicks from the homepage are often under-crawled, so they go to the top of the check list.
Treat the crawl as a starting point, not a verdict. It reports what it can reach from your start URL, not what Google has chosen to index. Confirm each finding against Google Search Console and log data in later steps, since the same issues often surface in search results before they appear in a crawl report.
Finding and fixing broken links, redirect chains and crawl errors
Broken internal links (4xx responses) waste crawl budget and strand users. Fix the source link where you can, since that removes the problem at its root.
Redirect chains slow crawling and can dilute signals. Point every redirect straight at its final destination. Verify the chain threshold for your tool against its current documentation before setting an alert.
Server errors (5xx) need a different response. If they cluster on specific templates or during load spikes, pass the affected URLs and timestamps to engineering. Check edge caching and CDN rules too, since they can change what crawlers receive, including for mobile users.
Not every error needs fixing. A 404 on a deliberately retired page is correct behaviour. Confirm intent before creating work for developers.
Auditing the sitemap and robots.txt for conflicts
Check three things:
- Sitemap URLs that return non-200 responses. A sitemap should list only canonical, indexable URLs.
- Sitemap URLs blocked by robots.txt. Google cannot crawl a disallowed page to see its content, so listing it is contradictory.
- Robots.txt blocks on resources a page needs. Never block Googlebot from JavaScript or CSS, since Google needs them to render the page. Google’s robots.txt documentation explains how the file is read.
Not every blocked URL is a problem. Faceted filters, internal search pages and admin paths are often blocked on purpose. If you want a URL ranking, it must be crawlable and in the sitemap. If you do not, block it or noindex it. Regular seo audits catch these conflicts before they accumulate.
Step 2: Check Indexation and Analyze Crawl Budget
Before you prioritise anything, find out what Google actually holds. Indexation is the gap between the pages you publish and the pages Google stores and can show. Crawl budget is the attention Googlebot gives your website. A website with thousands of wasted URLs can look healthy in a crawl report while its best pages stay unindexed. This step checks both, as part of any technical SEO audit, so that your work supports both search engines and a good user experience.
Comparing indexed pages against the pages you intend to rank
Export the URLs your crawler marked indexable, then compare them with the Pages report in Google Search Console. Log any indexable page that is missing from the index, or indexed but absent from your intended list, in a working spreadsheet. Slow pages that fail to load promptly, a common symptom of poor site speed, are often among the missing ones.
Score each mismatch in the Impact-Evidence Priority Matrix. Evidence is strong when the crawl export, Search Console status and a log-file sample agree. Impact is high for revenue or lead pages that should rank. A commercial category page marked “Crawled, currently not indexed” with no Googlebot hits scores high on both axes and goes straight to the priority fix list.
Spotting thin, duplicate and parameter URLs wasting crawl budget
Crawl budget problems usually come from URL sprawl, not site size. Filter the crawl export for three patterns:
- Thin pages: indexable URLs with little unique text, such as empty tag archives.
- Duplicates: the same content under several URLs, often through http and https or trailing-slash variants. Duplicate content of this kind splits signals across copies.
- Parameter URLs: sort and filter strings such as ?sort=price, which can multiply a few hundred products into tens of thousands of crawlable addresses.
Cross-check these against server logs. If Googlebot requests parameter URLs thousands of times a week while your money pages get a handful of hits, you have a confirmed leak. Log files show the search engine’s own view of your website, which a crawler simulation cannot.
Fix the leak at the source. Block low-value parameters in robots.txt, noindex thin pages you want kept for users, and consolidate duplicates with redirects or canonicals.
Manual Google search and indexing checks that confirm what the tools report
Verify the important cases by hand. Run a site:yourdomain.com query for a rough picture of what Google has indexed. Then use the URL Inspection tool on five to ten priority pages and read the “Indexing allowed?” and “Last crawl” fields. Searching an exact page title shows whether that page ranks at all. Performing a technical check of this kind alongside your other seo audits gives a fuller picture than any single tool.
Record each manual result beside the tool finding. If the crawler marks a page indexable but URL Inspection reports a noindex header, trust the Google signal and investigate the header. Disagreements between sources often point to a CDN or edge rule that returns a different response to Googlebot than to your crawler.
Step 3: Consolidate URL Canonicalization and Site Versions
Most websites serve the same page at several addresses: with and without www, over http and https, with and without a trailing slash, and at parameter variants created by filters or tracking. Search engines treat each address as a separate URL until told otherwise. Link equity and crawl budget then get split across copies of one page, and these duplicate-URL issues are among the most common reasons a site underperforms in search. Thorough seo audits surface these duplicates early, before they dilute rankings.
Choosing one preferred version of each URL
Decide the canonical form for each page type: protocol (https), host (with or without www), and trailing-slash convention. Recording this important decision in your audit notes before changing any setting keeps the team aligned. Then request each variant and read the status code and final URL.
Use this checklist to test each variant:
- Request http and https, with and without www, and with and without a trailing slash.
- Confirm every non-preferred variant returns a single 301 redirect to the preferred URL.
- Confirm the preferred URL returns a 200 status and a self-referencing canonical tag.
- Check that your XML sitemap lists only the preferred form.
Fixing http, https, www and trailing-slash duplicates
Protocol and host duplicates are usually fixed at the server, CDN or load balancer with permanent redirects. A 301 tells search engines to consolidate signals onto the destination. If your site runs behind a US cloud host with a CDN, check edge rules as well as the origin. A cached 200 on a duplicate can hide a missing redirect, so use crawling tools to confirm the redirect is actually working.
Pick one trailing-slash convention, redirect the other, and make sure internal links point only to the chosen form. Consistent internal linking helps search engines find the preferred URL.
Canonical tags, redirects and the errors that undo them
A canonical tag is a hint, not a directive. It works best when it agrees with your redirects, sitemap and internal links. When these signals conflict, search engines choose the URL they consider most authoritative, which may not be yours.
| Symptom in your crawl | Likely cause | Fix |
|---|---|---|
| Canonical points to a URL that redirects | Canonical targets a non-final address | Point canonical at the final 200 URL |
| Page canonicalised to a different page | Template sets one canonical for every page | Make canonicals self-referencing per page |
| Redirect chain of two or more hops | Old redirect left after a migration | Collapse the chain to one 301 |
| Sitemap lists a non-canonical URL | Sitemap generated from unfiltered data | Filter sitemap to canonical URLs only |
Verify fixes in your crawl export and in the Page indexing report in Google Search Console, which shows the canonical Google selected for each URL. Use these SEO tools to cross-check results. If Google’s choice differs from yours, investigate before assuming the redirect or tag is at fault.
Step 4: Analyze JavaScript Rendering and Crawlability
Googlebot downloads the raw HTML, queues the page for rendering, and only then reads content added by JavaScript. Any gap between those stages can cause content to go missing from the index. This step checks that gap directly across the website as part of a broader site audit.
Comparing rendered and raw HTML
Pick ten to twenty templates that represent the site, such as a homepage, a category page, a product or article page, and a filtered or paginated view. For each one, compare the page with JavaScript disabled against the same page with JavaScript enabled. The difference is what depends on rendering.
Run the same URLs through a crawler that supports JavaScript rendering. Screaming Frog, for example, lets you compare raw HTML against the rendered DOM. Any internal link, heading, canonical tag or meta robots directive that appears only in the rendered version needs a decision: serve it in the initial HTML, or confirm that Google renders the page reliably. Rendering gaps can also surface duplicate content issues when the same text appears under multiple rendered URLs.
Keeping JavaScript and critical resources crawlable
Never block Googlebot from crawling JavaScript through robots.txt. Google needs script and stylesheet files to build the page. A disallow rule on a /js/ or /assets/ folder can leave the rendered page empty or broken. Lumar’s guidance on crawling strategy notes that almost nobody actually wants a full site crawl, so focus on the templates that matter. Use Search Console’s URL Inspection tool to confirm the live test loads the page as intended.
Check critical resources too. Content from a third-party API, a CDN file that returns errors to crawlers, or a script that waits for user interaction before loading will not reach the index. Flag these with the resource URL and the status code it returned. Errors affecting the mobile version of a page deserve the same priority, since Google indexes mobile-first.
Diagnosing content that Googlebot cannot see
When content is missing from Google’s index, check in order. First, confirm the content appears in the rendered HTML from your crawler. Second, use URL Inspection in Google Search Console to compare the rendered screenshot and HTML with what you expect. Third, search the search engine for a distinctive sentence from the page in quotes. If rendering is complete but search results show nothing, the problem is more likely indexation, which belongs in Step 2.
Log a finding only when you have evidence: a crawl export row, a URL Inspection result and a sample of the affected URL. Technical SEO audits that record evidence this way give the user experience team facts to act on, rather than assumptions. Document each issue with its URL and status so that on-page SEO fixes and technical fixes can be prioritized together.
Conclusion and Next Steps
How to schedule the audit and track whether fixes worked
A technical audit is only worth the effort if it ends in a ranked fix list and a way to confirm the fixes landed. Use the Impact-Evidence Priority Matrix to rank the work, then schedule and track it to prove results. Run a full audit every three to six months, as Webyes recommends, and keep lighter checks running between them.
Automate what can be monitored: crawl errors, redirect chains, indexation counts in Google Search Console, and Core Web Vitals field data. Fix a calendar date for each full crawl so baselines stay comparable.
To confirm a fix worked, compare before and after: the crawl export row count for affected URLs, the matching Pages report status, and weekly Googlebot hits in your log files. A fix that cleared a crawler warning but left log data unchanged has not changed what search engines do.
Record each finding with its baseline, ticket reference and re-check date. This log is your evidence of what the audit achieved.
Frequently Asked Questions
How long does a technical SEO audit take?
A full audit of a small site, with a few hundred URLs, takes one to three days. Larger sites take longer, with the time going to crawl analysis and developer reproduction of issues. Reading the results and confirming which findings are real is usually the slowest part. A comprehensive audit commonly takes three to six weeks, while international, ecommerce or JavaScript-heavy sites may require longer.
Which tool should I start with if I have a small budget?
Start with Google Search Console, which is free and shows how Google sees your indexation and Core Web Vitals. Pair it with Screaming Frog’s free crawler, which covers up to 500 URLs. That is enough to find broken links, redirect chains and canonical conflicts. Once you can read crawl data, compare seo tools for small businesses before paying for a crawler.
How is a technical audit different from a content or backlink audit?
A technical audit checks whether search engines can crawl, render, index and understand your pages. A content audit asks whether those pages deserve to rank. A backlink audit reviews the links pointing to your site. A noindex tag on a key page cannot be fixed by writing better copy.
Can I run a technical SEO audit without developer help?
You can run the crawl, read the indexation reports and build a prioritised list alone. You will need a developer for anything that changes server responses, templates, robots.txt rules or rendering. Attach the crawl export, the Search Console URL sample and log-file hits to each ticket so the developer can reproduce the issue.
How do I know when an audit is finished?
An audit is finished when every finding is scored, every high-scoring item has an owner and a ticket, and you have a re-crawl date. If you cannot say what would prove a fix worked, the audit is still an inventory, not a plan.
Disclosure: digitalmarketingtools.ai is sponsored by Digimetrics.ai. Sponsored Highlights are clearly labelled advertising. Our reviews, comparisons and guides are written to be useful and fair regardless of who sponsors the site. Read the full disclosure.